Content
dbt Summit 2026 reframed the semantic layer as AI infrastructure. What it means for enterprise data leaders, and how to tell if your data is ready for agents.
At dbt Summit 2026, the semantic layer stopped being a BI convenience and became part of the infrastructure that decides whether AI agents can be trusted with your data. If agentic AI is on your roadmap, a governed semantic layer is now a prerequisite, not an optimization.
dbt Labs renamed its flagship conference from Coalesce to dbt Summit (September 15-18, Las Vegas) and rebuilt the agenda around one idea: AI-ready data. The headline product news – the dbt Semantic Layer with MetricFlow and MCP – all pointed the same direction. Governed metric definitions are becoming the interface AI agents use to read your business. We looked at the wider move in our dbt Summit 2026 recap on analytics engineering and AI; this piece zooms in on the semantic layer itself.
Written for CIOs, CDOs and heads of data, it covers what that shift means, where it exposes risk in a real data estate, and how to decide whether your data is ready before you point agents at it.
What dbt Summit 2026 signaled
The rename from Coalesce to dbt Summit was not cosmetic. It repositioned the transformation layer, and the semantic layer inside it, as foundational infrastructure for AI rather than tooling for building dashboards.
A semantic layer is a single, governed set of business definitions – metrics like “active customer” or “net revenue,” plus the dimensions and logic behind them – that sits between your data warehouse and everything that reads from it. For years that “everything” meant BI and reporting tools. The change dbt made explicit is that it now includes AI agents.
The product news from the summit clustered around that one idea. The dbt Semantic Layer, MetricFlow and a Model Context Protocol (MCP) server were presented together as governed context that agents can query through a standard interface. Supporting announcements – the Fusion engine, dbt State (which dbt reports cuts average compute by roughly 30%) and open Apache Iceberg storage – framed the whole stack as durable infrastructure, not a point tool.
The keynote made it explicit. The “Level Up” session framed data teams getting ready for “the agentic era,” while hands-on labs had practitioners standardize metrics in the dbt Semantic Layer and confirm they hold downstream.
Put it together and the takeaway is plain. The semantic layer is where analytics engineering now meets AI, because it is the one place an agent can get your numbers right.
The enterprise problem: agents need meaning, not columns
An AI agent can read your schema. It cannot read your intent. That gap is the problem dbt Summit kept circling back to.
A model generates SQL in seconds, but it cannot know what your business means by “active customer,” which revenue figure is the reported one, or whether last night’s pipeline actually ran. That knowledge lives in definitions, tests and lineage – the semantic layer – not in the raw tables.
Give an agent undefined data and it will still answer, confidently, and sometimes be wrong. A plausible wrong number in a board pack is worse than no number, because someone acts on it. For a CIO or CDO, that is not an analytics inconvenience but operational risk, the lens this audience buys through.
So the scarcest resource is not compute or model capacity. It is consensus: one agreed definition of each metric that the whole company, and every agent, uses. Teams at the summit, including Ramp, described the semantic layer as effectively an API to the warehouse. Agents route through it instead of querying raw tables, so every answer inherits the same governed meaning, lineage and access rules.
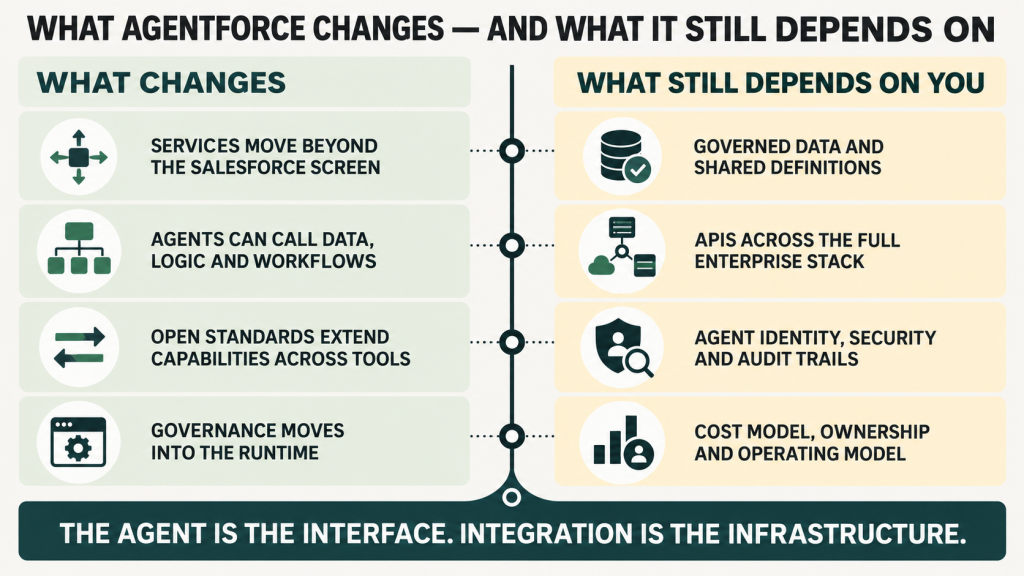
Before you let an agent touch your data, ask one question: will it answer in your company’s terms, or in its own best guess? Most AI pilots stall right there, on whether the data is genuinely AI-ready.
What changes in your architecture, governance and cost
Once the semantic layer becomes infrastructure, three things change in how you run it.
| The shift | What it means in practice | Why it matters to leaders |
|---|---|---|
| Own it as shared infrastructure | A headless, tool-agnostic layer (a metrics layer, or headless BI) owned by analytics engineering, versioned and reviewed, with a named owner for every definition. | One source serves agents, BI and applications at once. Someone is accountable when a definition like “net revenue” moves. |
| Keep it portable | Open formats like Apache Iceberg and a universal semantic layer above the warehouse, so you can swap an engine or BI tool without rebuilding definitions or losing lineage. | The practical hedge against vendor lock-in for hybrid and multi-cloud estates. It is why IBM watsonx.data and Microsoft Fabric integrations mattered more than any single feature. |
| Govern access and cost | Access control and data governance for AI extended into the layer; tests and contracts pass before anything reads; cost visibility (dbt State) on by default. | Agents see only the metrics and rows their role allows. Spend stays predictable when agents generate far more queries than people do. |
All three come back to ownership. A semantic layer only works as infrastructure when a team runs it as a product, not as a setting buried inside one BI tool.
A decision framework for enterprise leaders
You do not need every metric in a semantic layer before you start. You need a defensible sequence. Use this before you point an agent at production data:
- Pick the decisions first. Start from the handful of metrics agents will actually use, not the whole warehouse.
- Define them once. Agree a single governed definition per metric and put it in the semantic layer.
- Prove it holds. Add tests, contracts and lineage so the number is correct and traceable from source to answer.
- Set the guardrails. Apply access control and freshness SLAs before any agent connects.
- Then scale. Expand coverage metric by metric, watching cost as query volume grows.
A semantic layer is AI-ready when you can tick all of these:
- One agreed definition for each core metric, shared across teams and agents
- Tests and data contracts that run before anything downstream reads
- End-to-end lineage from source to the agent’s answer
- A named owner for every definition, and the right to change it
- Freshness SLAs treated as an AI service level, not a nice-to-have
- Fine-grained access control over what each agent can see and do
- A cost model that keeps spend predictable as usage scales
The order matters. Teams that define, test and govern first are the ones whose AI-augmented BI and agents reach production instead of stalling in pilots.
Key takeaways
- dbt Summit 2026 (formerly Coalesce) reframed the semantic layer as AI infrastructure, not a BI feature.
- AI agents need governed meaning – definitions, tests, lineage – not just access to tables.
- The scarce resource is consensus: one agreed definition per metric, used by people and agents alike.
- Run the semantic layer as owned, portable, governed infrastructure, with cost visibility built in.
- Define, test and govern a few key metrics first, then scale only once they hold.
Is your semantic layer ready for AI agents?
We fix the definitions, tests, lineage and governance underneath your data – so analytics and AI agents run on numbers people actually trust.
Context first. Agents second.
Context first. Agents second.
Related services: AI Data Integration Solutions · Modern Data Architecture · Data Governance Services and Consulting
FAQ
What is a semantic layer?
A semantic layer is a single, governed set of business definitions – metrics, dimensions and the logic behind them – that sits between your data warehouse and the tools, and now the AI agents, that read from it. It gives everyone one version of each number.
Why do AI agents need a semantic layer?
A model can write SQL, but it cannot infer what your business means by a metric. The semantic layer supplies governed definitions, so an agent answers in your company’s terms instead of guessing from column names.
What is the difference between a semantic layer and an ontology?
A semantic layer defines business metrics and dimensions for analytics and agents to query. An ontology describes broader relationships and meaning between concepts across a domain. They overlap, but a semantic layer is narrower and metric-focused.
Is Snowflake or Databricks a semantic layer?
Not on their own. They are platforms that can host or integrate a semantic layer (for example, Databricks metric views), but the semantic layer itself is the governed definition layer above the warehouse, ideally portable across engines.
Is the dbt Semantic Layer the same as MetricFlow and MCP?
They work together. MetricFlow compiles metric definitions, the dbt Semantic Layer serves them consistently, and the MCP server exposes them to AI agents through a standard interface.
Sources
- dbt Summit 2026 – Agenda
- dbt Summit 2026: the keynotes and product sessions
- A preview of dbt Summit 2026 sessions by role
- Semantic Layer: what it is and when to adopt it – dbt Labs
- Why a semantic layer is pivotal to your AI strategy – MIT Sloan
- What is a semantic layer? – IBM
- The scarce resource is consensus (Ian Macomber) – dbt roundup